Nifty RL Trading Results
Reinforcement Learning trading strategy using PPO
This is a short / bounded training run (80,000 timesteps on CPU) for research purposes only. It is not a production model and not intended for live trading. The agent still shows a negative absolute return (-6.40%), though it outperforms buy-and-hold by +5.29 percentage points.
Changes for Nifty: Indian equity index data, IST timezone, adjusted trading costs, calendar-based splits
Key Results Summary
PPO Agent
554 trades • 42.78% win rate
Max DD: -13.27% • PF: 0.948
Final equity: 9,360
Buy & Hold
1 trade (hold entire period)
Max DD: -15.72%
Final equity: 8,831
Excess Return
Agent outperforms baseline by
5.29 percentage points
(still negative absolute return)
Equity Curve — Test Period
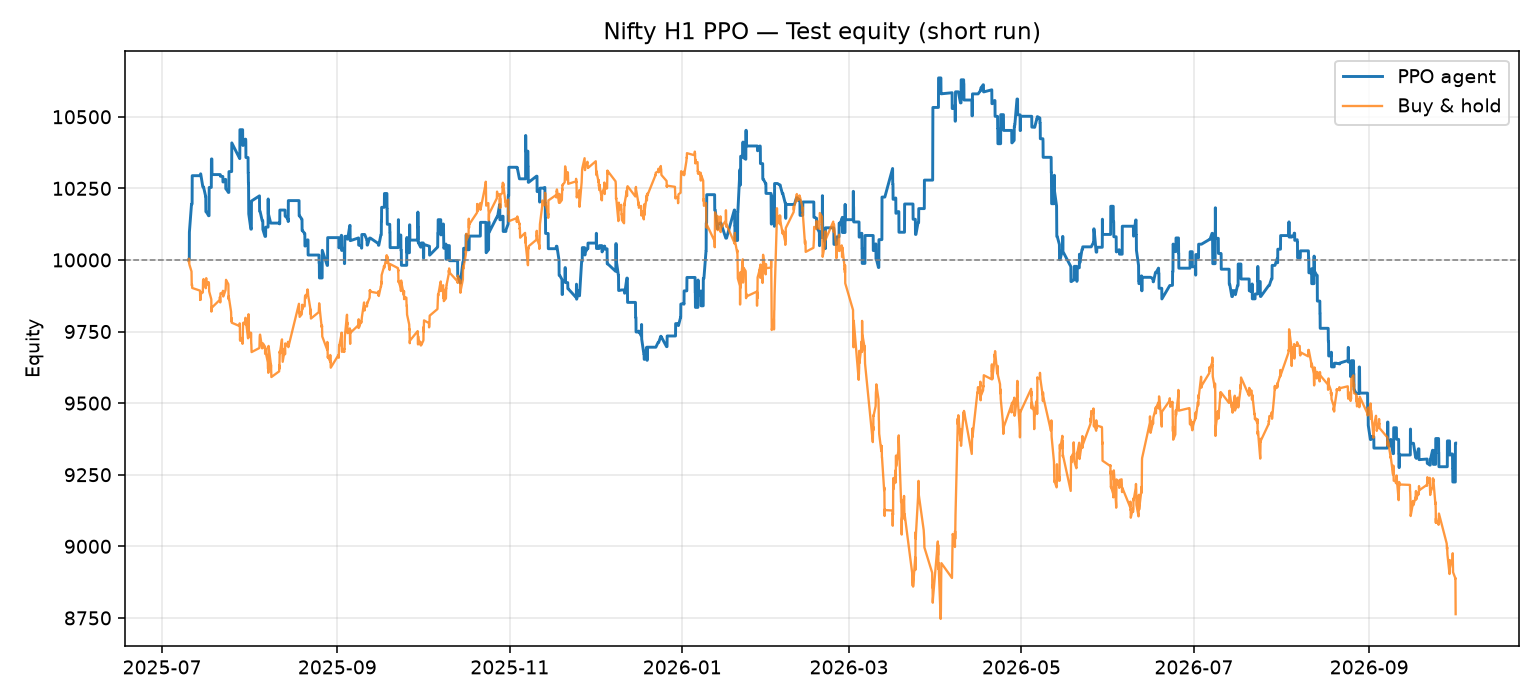
Test Metrics (2025-07-10 to 2026-10-01)
| Metric | PPO Agent | Buy & Hold |
|---|---|---|
| Total Return | -6.40% | -11.69% |
| Max Drawdown | -13.27% | -15.72% |
| Final Equity | 9,360 | 8,831 |
| Number of Trades | 554 | 1 |
| Win Rate | 42.78% | — |
| Profit Factor | 0.948 | — |
| Excess vs B&H | +5.29 pp | — |
Data Splits
| Split | Start Date | End Date |
|---|---|---|
| Train | 2022-02-22 | 2024-12-19 |
| Validation | 2025-01-10 | 2025-06-19 |
| Test | 2025-07-10 | 2026-10-01 |
Data: Nifty 50 1-minute bars (440,167 bars total from 2022-01-03 to 2026-10-01 IST)
Source: s3://analyticsdata123/options-ml-platform/data/timeframes/1m/nifty50.parquet (region ap-south-2)
Method Summary
Algorithm
- RL Algorithm: PPO (Proximal Policy Optimization) via stable-baselines3
- Training timesteps: 80,000 (short run, CPU)
- Seed: 42
- Initial equity: 10,000
Decision & Execution
- Decision timeframe: H1 (hourly bars resampled from 1-minute data)
- Execution timeframe: 1-minute (for intrabar TP/SL fills)
- Action space: Gymnasium MultiDiscrete [direction, SL ATR bucket, TP R-multiple bucket]
- Stop-loss ATR multipliers: [1.0, 1.5, 2.0]
- Take-profit R-multiple buckets: [1.0, 1.5, 2.0, 3.0]
- Fill order: Stop-loss first (SL-first), then take-profit
Features & Reward
- Observations: 25 causal ATR-normalized features + 6 position features
- Reward: Risk-normalized realized PnL + light MTM shaping − holding penalty
Trading Costs (Nifty index points)
- Spread: 1.0
- Slippage: 0.5
- Commission: 2.0 per trade
- Note: These are rough estimates for liquid index futures
Limitations & Next Steps
Limitations
- Short training run (80k timesteps) — not sufficient for production validation
- Single chronological split — no walk-forward or rolling window validation
- CPU training only (slow convergence)
- Rough cost estimates — actual costs may vary by broker and instrument
- Negative absolute returns — agent loses money despite outperforming buy-and-hold
- Test period may not be representative of other market regimes
Potential Improvements
- Extend training (500k–2M timesteps on GPU)
- Implement walk-forward validation across multiple periods
- Tune hyperparameters (learning rate, batch size, network architecture)
- Add regime awareness (trend/range detection)
- Incorporate additional features (order flow, volatility regime, market breadth)
- Test with actual broker costs and constraints
- Validate on out-of-sample data from different years/regimes
Files & Code
This project is part of the s1a2t3y4/trading_algo monorepo under
aiprojects/rl-trading-nifty/.
README.md — Documentationrun_nifty_ppo.py — Main training & evaluation runnernifty_data.py — Parquet loader for Nifty 1m barsrequirements.txt — Python dependenciesmodels/ppo_H1_sl1-1.5-2_tp1-1.5-2-3_80k_seed42.zip — Trained model checkpointresults/ — Test results (metrics, equity, trades, charts)
Upstream source: github.com/ZiadFrancis/Reinforcement_Trading_Part_2
Legal & Disclaimers
This repository is for education and research purposes only. Nothing here is investment advice. Past backtest results do not guarantee future performance. The strategy shows a net loss on the test period and should not be used for live trading without extensive further validation, risk management, and paper trading.
Note: The matching VecNormalize pickle is not included in the repo. To reload the policy for inference, you will need to retrain or provide the vecnorm file separately.
Generated: Oct 4, 2026 • Test period: Jul 10, 2025 – Oct 1, 2026